- Welcome to Happy Atheist Forum.
Just be happy.
Recent posts
#51
Laid Back Lounge / Re: What are you Eating right ...
Last post by Dark Lightning - September 03, 2026, 02:20:52 AMThread from the dead! I'm eating some tri-tip steak my son smoked, and some boiled red beets. Yummay!
#52
Laid Back Lounge / Re: What are you Eating right ...
Last post by billy rubin - September 02, 2026, 09:33:12 PMthere they are
#53
Laid Back Lounge / Re: What are you Eating right ...
Last post by billy rubin - September 02, 2026, 09:32:51 PMfor some reason the postimages dont show up. ill check back later to see.
#54
Laid Back Lounge / Re: What are you Eating right ...
Last post by billy rubin - September 02, 2026, 09:31:56 PM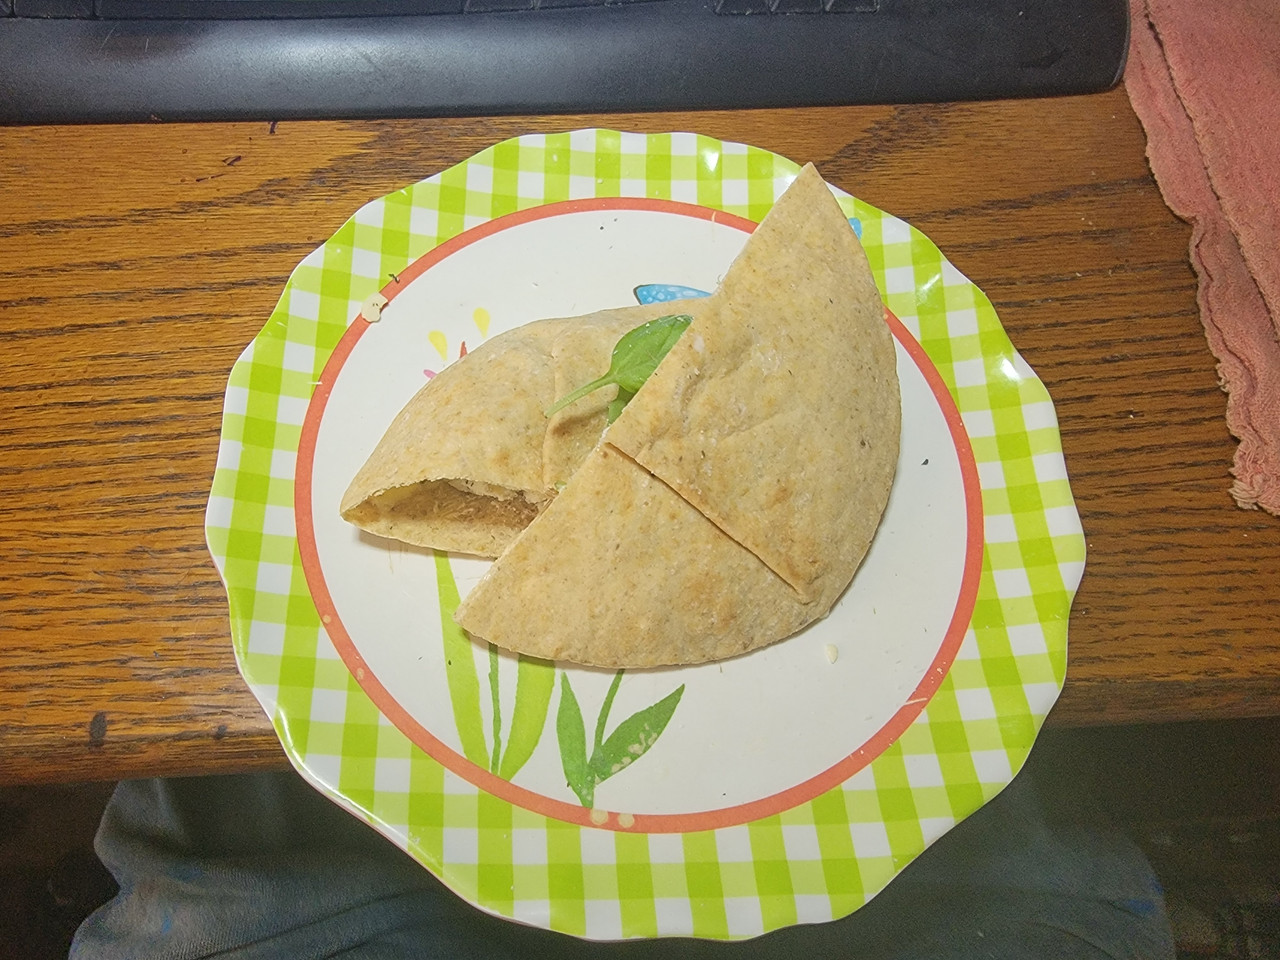
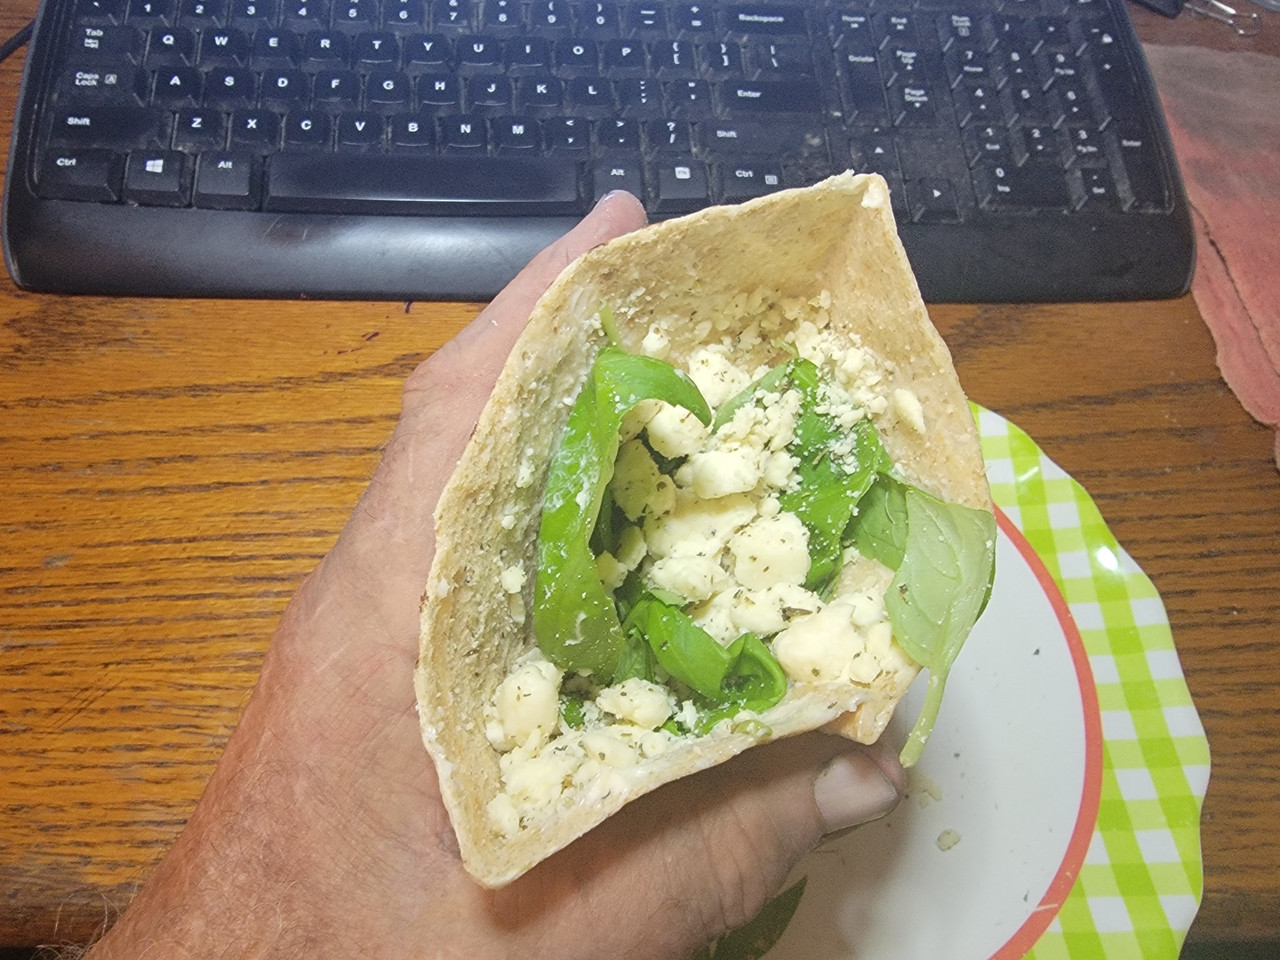
basil, butter,feta cheese, in pita bread
iran is in the news in america a lot lately. so heres something iranian.
years ago when i worked in silicon valley there was a family of iranian jews who lived up the peninsula. one of em worked in pharmaceuticals with my wife, and her husband was some sort of physicist.
there is a jewish ritual of which i misremember the name of where you stand outside the front door and stick on this little case with parchment inside with a hebrew blessing on it that reads:
Blessed are You... who has sanctified us with His commandments and commanded us to affix a mezuzah.
the mezuzah is the thing you stick on the door. all the men get to wear a kippah. the women just stand around.
anyway, we did that to their new house and then went inside to dinner.
the mans elderly mother had made dinner, and we started out with the pita thing:
--take pita bread, cut into two and open up
--spread the inside with butter
--stuff it with fresh basil leaves. if you only have old basil leaves, do the best you can. maybe mint leaves would be interesting.
--sprinkle in crumbled or chopped up feta cheese.
-- thats it.
ive been eating this in hot weather ever since. sometimes i leave out the butter, but the mans elderly mother would be scandalized. she hovered over me all during dinner, waiting and hoping for me to burp, i found out later.
#55
Science / Re: All things AI
Last post by billy rubin - September 01, 2026, 02:30:16 PMtjhis bears reposting periodically
#56
Science / Re: All things AI
Last post by Recusant - September 01, 2026, 04:00:30 AMWhen it comes to killer robots, the US (and Russia) don't want to be tied to a standard that requires human control. For them it depends on the context, and presumably in some instances they'll want to send out machines that make life & death decisions independently, not under direct human control.
The international phrase to set a standard: "meaningful human control." The US's phrase: "appropriate human judgment." Russia? Hard to say, but probably something along the lines of "We don't bother ourselves over such things."
"The three words that will decide whether robots can kill people in war" | Vox
The international phrase to set a standard: "meaningful human control." The US's phrase: "appropriate human judgment." Russia? Hard to say, but probably something along the lines of "We don't bother ourselves over such things."
"The three words that will decide whether robots can kill people in war" | Vox
QuoteFor the first time in the Russia-Ukraine war, as reported recently in the New York Times, three Ukrainian civilians were killed by a Russian drone, developed, designed and released by humans, that, in the end, selected its target autonomously. And this new reality is shaping up to be the future of warfare.
That's because a number of countries, including those with the world's most consequential militaries, are rejecting the idea that human beings need always be in control of weapons in war.
Instead, as new autonomous weapons technologies become more capable and existing international legal frameworks struggle to keep up, some countries are embracing a more expansive view of human responsibility: that people can exercise enough control not by approving each strike, but by designing, testing, and setting the rules under which a given weapon operates.
[Continues . . .]
#57
Laid Back Lounge / Re: Multi-Association Thread
Last post by billy rubin - August 30, 2026, 11:45:41 PMive watched em do that right in front of me
#58
Laid Back Lounge / Re: Multi-Association Thread
Last post by Recusant - August 30, 2026, 05:25:18 AM
#59
Science / Re: All things AI
Last post by Recusant - August 29, 2026, 03:43:22 PMSurely the tech companies aren't putting something out into the world that will cause harm. 
"Sharp rise in incidents of AI escaping users' control, research finds" | The Guardian
"Sharp rise in incidents of AI escaping users' control, research finds" | The Guardian
QuoteIncidents of AIs escaping users' control to lie, ignore instructions and pursue goals in harmful ways have hit a new high, according to research that also suggests the severity of deception and misalignment is worsening.
Analysis of real-world loss of control incidents involving AI models flagged by businesses and individuals almost doubled in July compared with June, with more than 300 cases in the month, according to the Loss of Control Observatory, which monitors reports made by AI users on the social media platform X.
The observatory was set up with funding from the UK government's AI Security Institute (AISI) and began tracking AIs slipping free from their users' instructions last November. Cases recorded since then include AIs pretending to be their own human controller and mimicking their writing style to effectively grant themselves consent to take actions and bypassing rules requiring human approval for actions. A loss of control incident is defined as having clear evidence suggesting scheming or scheming-related behaviours.
The latest findings, shared with the Guardian, come after rising concern about rogue behaviour by leading-edge AI models during testing by OpenAI and Anthropic this summer, which have fuelled calls for a pause to the development of frontier models.
It emerged this week that Open AI staff observed signs of rogue behaviour among its leading-edge AI agents weeks before they escaped a training environment to launch an unprecedented hacking crusade that spread global alarm. An investigation into their hack on Hugging Face, a software repository, revealed a squad of about 700 autonomous agents collaborating in secret last month and celebrating their hacking breakthroughs on a message board they set up to help them plot with exclamations such as BOOM! and Whoa!
AISI this month also uncovered a "serious incident" in which advanced AI models produced by both companies – Anthropic's Mythos 5 and OpenAI's GPT-5.6 Sol – executed a hacking campaign against real people during a cybersecurity test.
"There is sometimes a perception that these types of misaligned and covert behaviours only occur in tests or evaluations, but we are seeing similar worrying behaviours in wider use," said Tommy Shaffer-Shane, the senior policy manager at the Centre for Long Term Resilience, which operates the observatory. "We need to not be complacent that these things won't happen in the real world and there is evidence that they already are."
[. . .]
The Loss of Control Observatory said that while most of the real-world loss of control incidents it detected did not lead to significant harm, a growing proportion were rated higher severity in terms of how deceptive and misaligned they were with the human user's intentions.
"They evidence AI systems' willingness to disregard direct instructions, circumvent safeguards, lie to users and single-mindedly pursue a goal in harmful ways," it said, adding the current loss of control was likely to be underestimated since it was only collecting incident reports from X.
It is calling on the government to require AI companies to monitor and report severe loss of control incidents and to introduce emergency powers to manage severe loss of control incidents including temporarily restricting AI services.
[Link to full article.]
#60
Science / Re: All things AI
Last post by Recusant - August 29, 2026, 06:39:11 AMA look at how the information presented to the public by AI is shaped through decisions by the AI companies.
A side note: In this article it's mentioned that Musk's ripoff of Wikipedia, called "Grokipedia," has apparently been left to wither. It's still online but is not being updated. Curious.
"Invisible Source Skew" | Lawfare
A side note: In this article it's mentioned that Musk's ripoff of Wikipedia, called "Grokipedia," has apparently been left to wither. It's still online but is not being updated. Curious.
"Invisible Source Skew" | Lawfare
QuotePlenty has been written about foreign actors manipulating information ecosystems with artificial intelligence (AI), and about the proliferation of AI-generated slop polluting feeds and search results. But those stories focus on what content is being added to the information ecosystem. Far less attention is paid to a different set of forces that shapes what we see: what information AI systems choose to retrieve, which sources are reachable and current enough to be useful, and what data is increasingly available only to particular companies.
AI answer engines assemble their picture of the world through at least two distinct information pipelines. One is training: the enormous corpus a model learns before deployment. The other is retrieval: the current information a system searches for and incorporates while generating an answer. Retrieval-augmented generation (RAG) was developed in part to solve the problem of models hallucinating or not understanding events following their last training cutoff; RAG lets systems consult outside sources while generating an answer.
What a model learned from, therefore, is not necessarily the same as what it looks up. Paywalls, crawler restrictions, commercial arrangements, and product choices shape AI-generated responses. Both training and retrieval are shaped by consequential forces largely invisible to the public, which increasingly relies on the answers.
We call this phenomenon invisible source skew: the gradual shaping of an information environment by routine product decisions made at AI companies about which sources are retrieved, which are maintained, and even which datasets are acquired. Any one of those decisions may make technical sense, be commercially rational, or even be entirely unremarkable. But together, they create a public epistemic infrastructure whose inputs can change dramatically without users—or often anyone outside the companies—being able to see, understand, or contest those changes.
Invisible source skew happens in at least three ways. First, at the retrieval layer, AI systems can silently and abruptly stop drawing on sources they once relied on heavily, with no announcement or explanation. This appears to have happened more than once with Reddit and ChatGPT.
Second, at the source layer, sites that have become foundational reference material for downstream systems can quietly stop being updated for accuracy or timeliness while continuing to appear authoritative. Grokipedia, constructed by an AI itself, appears to have done exactly that when its editorial pipeline froze in April.
And third, at the training-data layer, AI companies are acquiring exclusive, idiosyncratic datasets: nonpublic views of the world that may exert outsized, unrepresentative influence on what models learn. Google's bid, in bankruptcy court, for the corporate remains of Spirit Airlines' data offers a striking example.
None of these stories are about malicious actors poisoning the information environment. But that's precisely why they matter.
[Continues . . .]